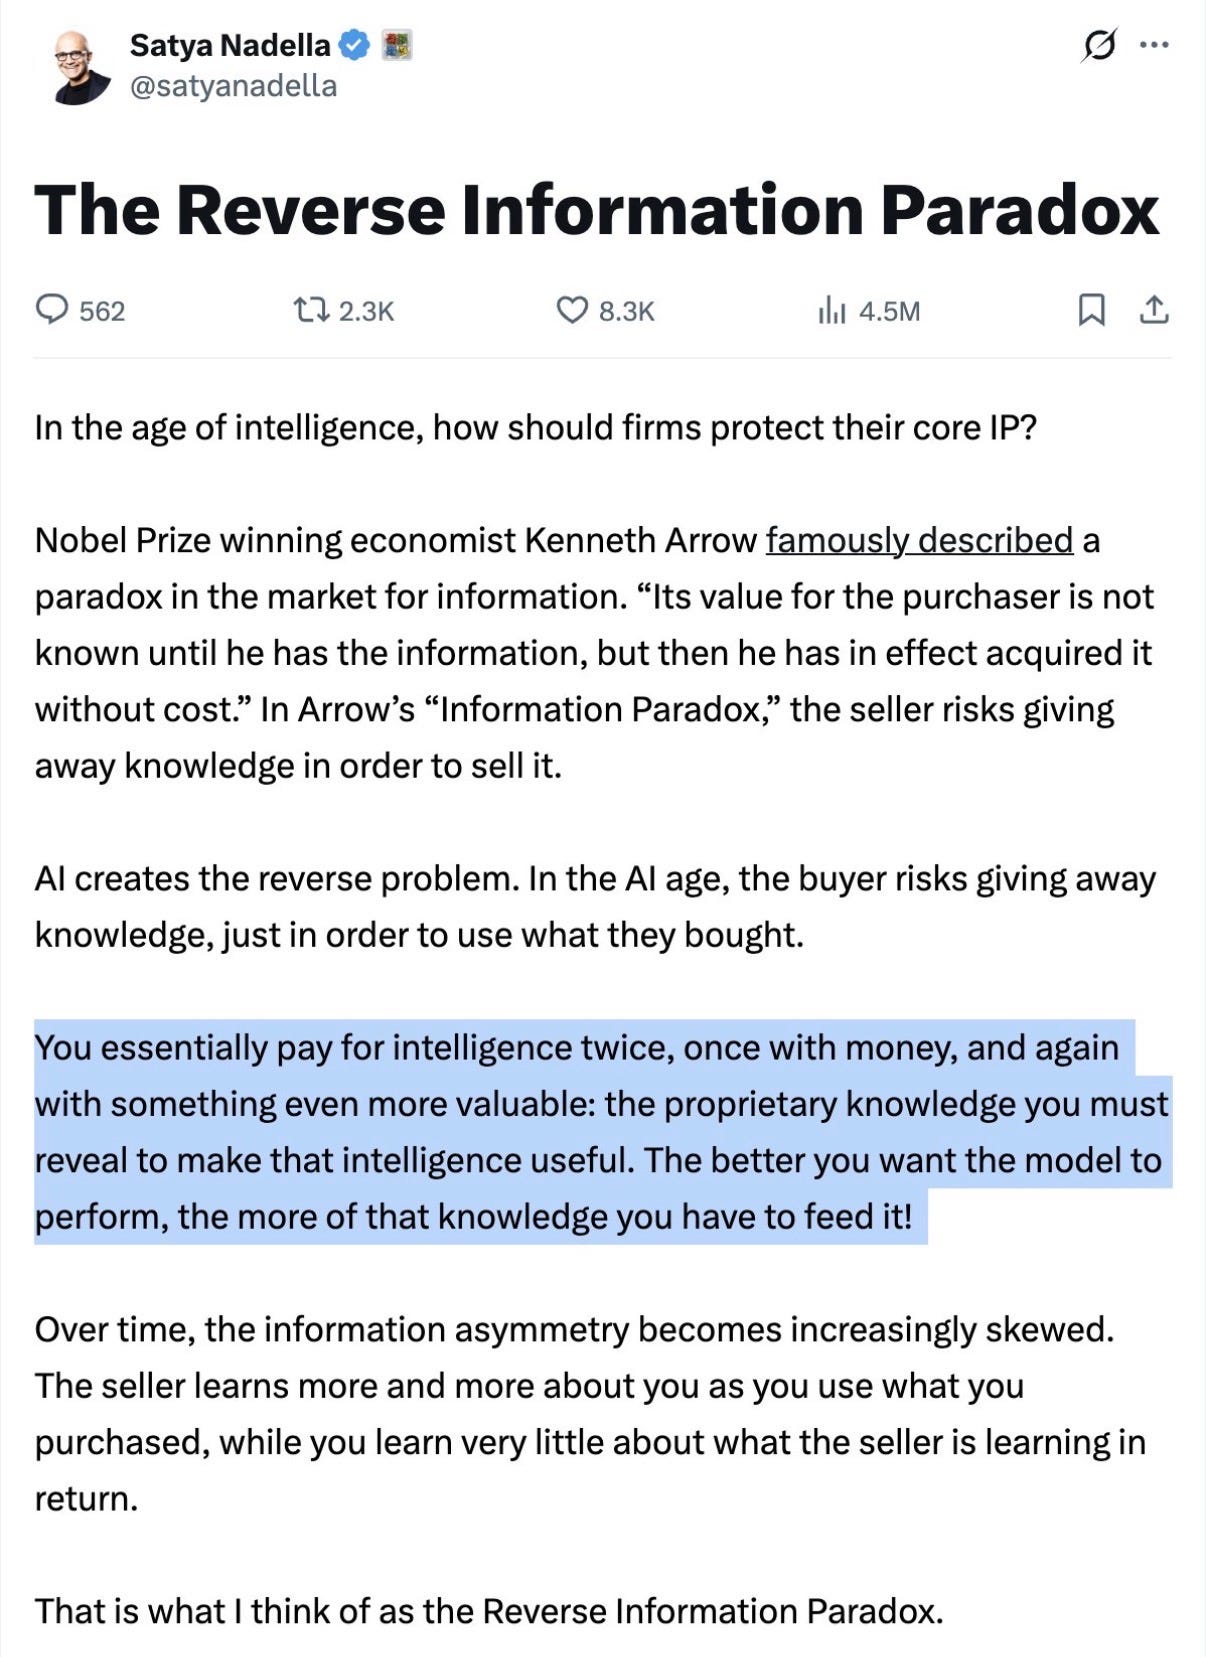
Satya Nadella recently introduced what he calls the “Reverse Information Paradox.” It caught my attention because it highlights a shift every executive team should be thinking about.
For years, the big question was:
Who owns our data?
That was the cloud era. The AI era asks something much more important:
Who owns the way your organization learns?
Every prompt, correction, evaluation, and workflow teaches an AI model something about your business. Not just your information—but your judgment, your processes, and what “good” looks like inside your company.
That’s institutional knowledge. And it’s one of the few competitive advantages competitors can’t simply buy.
Many companies still see AI as software.
It isn’t.
It’s a learning relationship.
Your employees are learning how to use AI. At the same time, the AI is learning how your business operates.
That’s why boards need to start asking different questions:
Who owns our evaluation frameworks?
Who owns the feedback loops and corrections?
Can we move models without losing what we’ve taught them?
Are we building capabilities—or dependencies?
It’s worth remembering that Nadella is also making a strategic argument that aligns with Microsoft’s interests. Every major AI company has a point of view on where enterprise intelligence should live.
But the bigger point stands. The cloud era was about protecting data.
The AI era is about protecting institutional learning.
The companies that win won’t just adopt AI faster. They’ll make sure the intelligence they create remains their own.
That may become the greatest competitive advantage of the next decade.
I actually like this version better for Substack and LinkedIn because it can be read in under three minutes while still leaving readers with one memorable takeaway: the shift from data ownership to institutional learning ownership.